Projects

All 8 systems.

08
systems

Demo available

Five systems you can watch running, one after another, with their measured figures and the way into each full record.

  1. 02Seeded legal-tech company

    Klaussa

    Indonesian law is scattered across 37 government sites, much of it only as scans.

    klaussa / chat
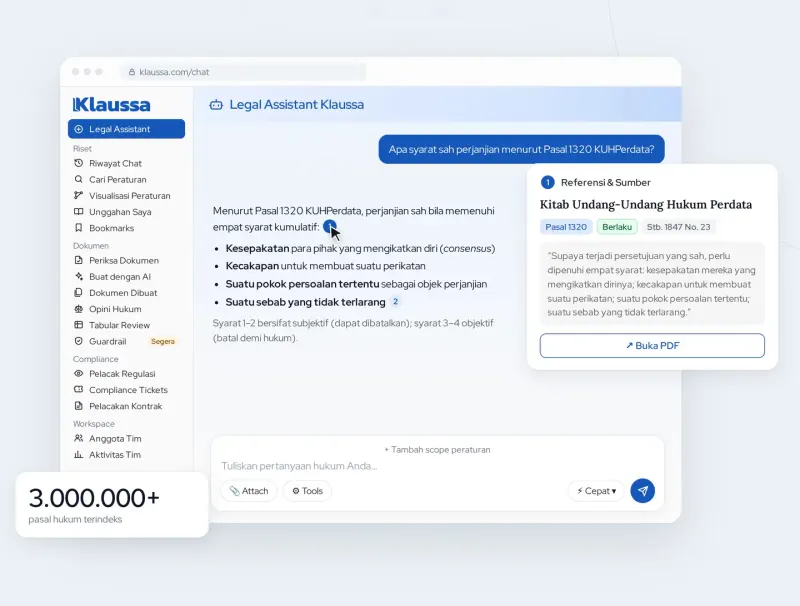
    Klaussa: Legal Assistant, the opening frame

    Legal Assistant. A legal question is answered from the corpus, with the plan it followed and the articles it relied on.

    Drawn product mockup: the company names, people and contract files in it are invented, while the regulations, article numbers and platform figures are real. The impact figures are recorded ones.

    It answers legal research questions from Indonesian regulations, with the source and citation trail attached.

    Impact

    297K
    regulations acquired from 37 sources
    3.48M
    vectors indexed
    2.57M
    citation edges at ~99% precision
    ~75×
    cheaper per query for Klaussa-8B than the hosted baseline, measured in evaluation

    Clips

    • FastAPI
    • Agno
    • Qdrant
    • Redis
    • Kubernetes
    • Cloudflare

    Open the full record

  2. 03Own research infrastructure

    Paperbase

    An agent cannot tell you whether your idea is already published.

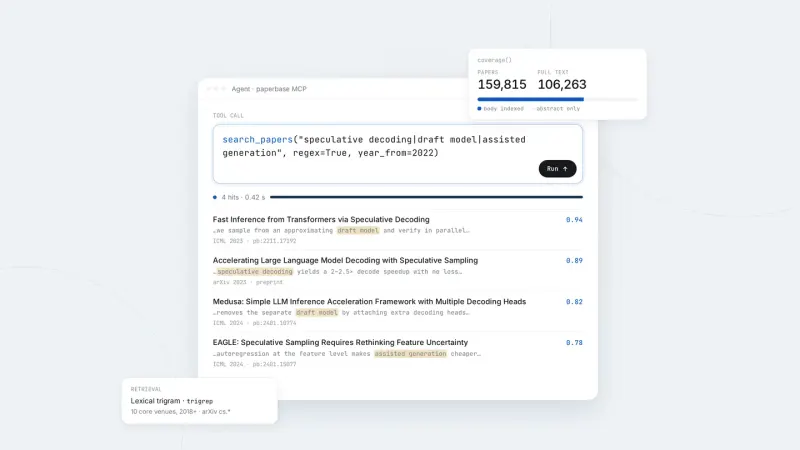
    paperbase / search_papers
    Paperbase: Search the corpus, the opening frame

    Search the corpus. A regex query over the full text returns ranked hits with the matching phrase in its own sentence, scored and dated, in well under a second.

    Illustrative product mockup: the tool names, the result shape and the corpus figures are real, and so are the papers on screen, though they were chosen to show the behaviour and not transcribed from a single run.

    An index of AI research that keeps itself current, which an agent queries through nine tools over MCP. The pipeline works down a venue roster, pulls each paper's metadata, fetches the arXiv PDF and extracts the full text, so a phrase buried in a body paragraph is findable. A paper outside the index comes back as a visible stub that one call will ingest.

    Impact

    159,815
    AI papers indexed
    106,263
    of them with full text extracted
    9
    query tools exposed over MCP
    10
    core venues swept, 2018 onward

    Clips

    Open the full record

  3. 04Klaussa · retrieval research

    Klaussa Retriever

    The law that answered the question sat at rank 14.

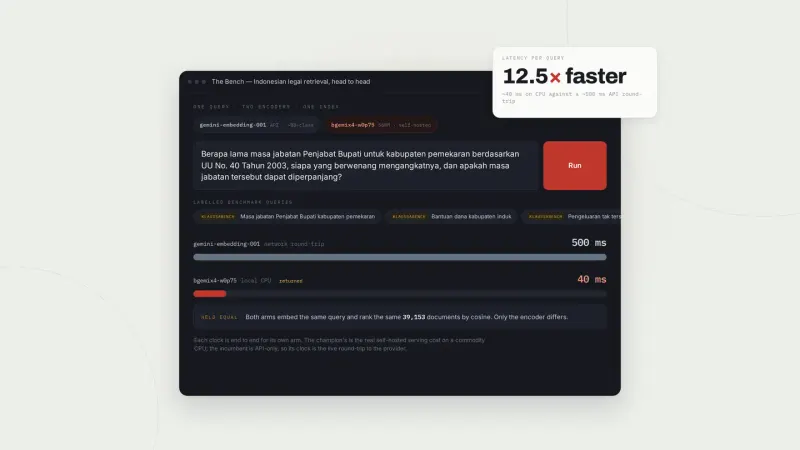
    klaussa-retriever / bench
    Klaussa Retriever: Ask, the opening frame

    Ask. One labelled query embedded by both encoders concurrently over the same 39,153-document index, each arm timed end to end: about 40 ms local against about 500 ms for the API round trip.

    Every number, latency and metric on screen is measured by the project's own evaluation kit. The ranked lists are arranged: each row is a real document from the index and the gold document's positions are the measured ones, while the documents filling the other slots were chosen to show the failure class and not transcribed from a run.

    Indonesian law has whole families of near-identical titles, and a general encoder ranks them on how similar the wording looks, so the one that actually governs can land at rank 14. A 568M-parameter retriever fine-tuned on this corpus puts it first, and answers in about 40 ms on an ordinary CPU against about 500 ms for the hosted API.

    Impact

    14 → 1
    rank of the governing document, this query
    12.5×
    faster per query, ~40 ms local against ~500 ms API
    0.496
    nDCG@10 on the agent register against 0.413, n = 803
    0.880
    nDCG@10 on the citation register against 0.856, n = 545

    Clips

    Open the full record

  4. 05Faculty of Pharmacy, Universitas Islam Sultan Agung

    ResepCerdas

    A prescription is written in Latin shorthand, and the patient has to take it correctly.

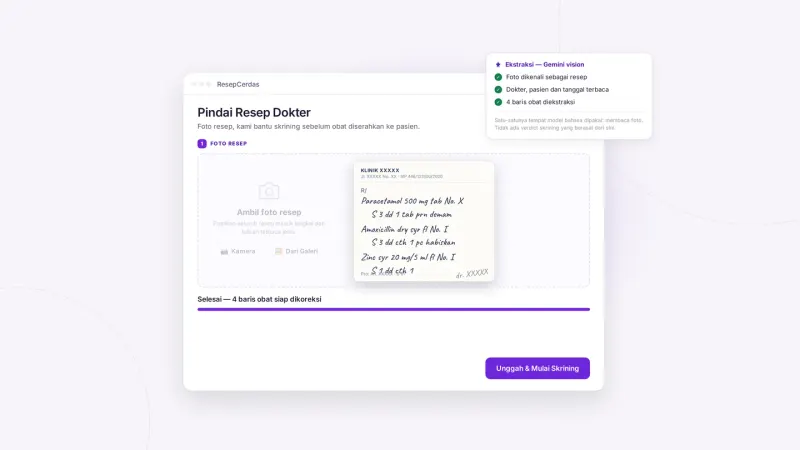
    resepcerdas / unggah
    ResepCerdas: Unggah — Upload, the opening frame

    Unggah — Upload. A photographed prescription becomes four structured drug lines. The satellite states that reading the photo is the only place a language model is used, and that no screening verdict comes from it.

    Illustrative product mockup drawn from the project's own tokens, status chips and finding titles. The prescription and the pharmacist's notes are from the project's synthetic corpus and the identities are masked; the pharmacist appears as a role, never as a named person.
    It turns a photographed prescription into corrected drug lines, then checks each line with 34 deterministic administrative, pharmaceutical, and clinical rules. No screening verdict comes from a language model.

    Measured

    34
    deterministic checks: 10 administrative, 10 pharmaceutical, 14 clinical
    19 / 19
    fields read on both benchmark fixtures, clean and degraded — synthetic handwriting, not a doctor's own
    2.2 s
    extraction latency on the clean fixture, 2.3 s on the degraded one
    10 of 40
    prescription images hand-labelled; the other 30, including all 20 real ones, are unlabelled

    Clips

    Open the full record

No demo available

Three systems with no clip and no page of their own, then the three bodies of data the systems were built on. Each corpus figure is a raw volume acquired, not an estimate of reach.